Industry Forum

Speech AI Industry Forum · Program
01

Tencent

Platinum Sponsor Session

Three speakers, three technical perspectives: from core speech capabilities to streaming dialogue, and onward to real-time voice agents that can invoke tools and accomplish tasks collaboratively.

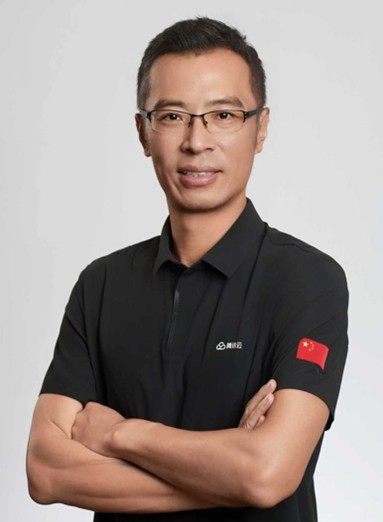
Shidong Shang
Shidong ShangTencent Meeting Tianlai Lab
Tencent Session 1

Understand Well, Speak Well, Communicate Without Boundaries — Tianlai Speech Foundation Model, Fully Upgraded

Shidong Shang |Director, Tencent Meeting Tianlai Laboratory; Member, AI Committee of the China Institute of Communications; Member, CCF Speech Dialogue and Auditory Special Committee

Abstract

From recognition, synthesis and enhancement to voice agents — how can speech AI truly serve hundreds of millions of users? The talk introduces Tencent Cloud's speech AI solutions for recognition, synthesis and spoken-language assessment, along with Tianlai Lab's advances in long-form audio recognition, Context ASR, OCR ASR, speaker diarization and separation, far-field recognition, and cross-channel speaker verification. It also covers recent explorations in speech synthesis, judgment-document-related tasks, generative speech enhancement and voice agents, and discusses real user-experience challenges across Tencent Meeting, Yuanbao, the input method and cloud speech PaaS.

Biography

Shidong Shang is Director of the Tencent Meeting Tianlai Laboratory. With over 20 years of experience in audio and video, he was formerly Senior Director of Dolby's China and Australia R&D teams; he joined Tencent in 2019 and leads R&D and productization of real-time audio analysis, processing and evaluation.
Dong Yang
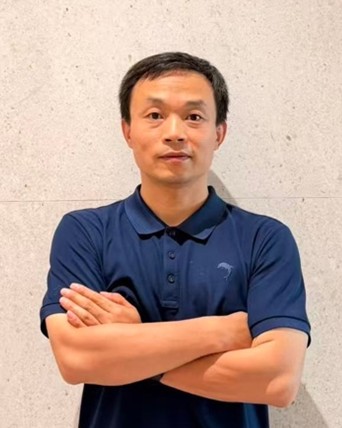
Dong YangTencent Game Voice
Tencent Session 2

Unified Streaming ASR and Word-Level Turn Detection with Interleaved Audio-Text LLMs

Dong Yang |Head of Game Voice Algorithms and Expert Researcher, Tencent

Abstract

In real-time voice dialogue, a system must know not only "what was said" but also "when to take the turn." Gvoice-Turn unifies streaming speech recognition and word-level turn detection through interleaved audio-text modeling with a dual-head architecture, predicting five states — completed, incomplete, backchannel, holding, and idle — while generating the transcript. Combined with CTC-prefill and a deferred-decision mechanism, it improves initial-recognition stability and revises recent decisions using subsequent context. The talk presents the architecture, the word-level streaming benchmark, and experimental results, discussing the trade-offs among accuracy, turn-taking decisions and interaction latency.

Biography

Dong Yang is Head of Game Voice Algorithms and Expert Researcher at Tencent. His research covers real-time speech enhancement, speech recognition, speech synthesis and intelligent voice dialogue systems.

Nova
NovaTencent Hunyuan
Tencent Session 3

From Voice Dialogue to Task Collaboration: Industrial Practice of a Voice-Interaction Foundation Model

Nova |Senior Researcher, Tencent Hunyuan

Abstract

The next step for voice agents is to move from natural conversation to proactively acquiring information and collaborating on tasks. Centered on Tencent Hunyuan's Hy-Realtime family of real-time voice-interaction foundation models, the talk demonstrates capability and iterative practice along three dimensions — spoken dialogue, search augmentation and agentic intelligence — and shares experience in reinforcement learning and tool-call capability building. It further discusses a dual-system architecture combining real-time interaction with deep reasoning, exploring the evolution from natural dialogue to complex task execution.

Biography

Nova is a Senior Researcher at Tencent Hunyuan, a core contributor to Hy-Realtime-3, and deeply involved in reinforcement learning and tool-call capabilities. First author of WavTokenizer, WavChat and other papers, and corresponding author of Gander, with 30+ papers published at CCF-A conferences, his research focuses on reinforcement learning and speech agents.

02

Xiaomi Corporation

Xiaomi Corporation
Lichun Fan
Lichun FanXiaomi
Forum Talk

From the Cocktail Party to Hot-Word Retrieval — Breaking Through Hard Scenarios for Large-Model ASR

Lichun Fan |Head of Speech Interaction, Technical Committee, Xiaomi Corporation

Abstract

Focusing on hard problems such as the cocktail-party scenario, hot-word retrieval and recognition, this talk shares breakthroughs in deploying large-model ASR. It covers four difficult scenarios: improving overlapped-speech recognition with CocktailASR; handling long-tail terms such as domain terminology and person names through efficient hot-word retrieval; enhancing transcription accuracy by fusing dialogue history with hot-word context; and building a business-oriented ASR evaluation system. Drawing on published papers, open-source code and production validation, it shares reusable engineering experience for large-model ASR in real end-device scenarios.

Biography

Lichun Fan received his PhD from the Institute of Automation, Chinese Academy of Sciences, and heads speech-interaction efforts on Xiaomi's Technical Committee. With over a decade in speech, he now leads voice capabilities for Xiaomi's smart cockpit, smartphones and AIoT devices, spanning pickup, wake-up, speaker verification, ASR, TTS and full-duplex interaction.

03

Beijing HuiTing Technology Co., Ltd.

HuiTing Technology
Jie Hu
Jie HuHuiTing Technology
Forum Talk

Insights into Hot Topics in Speech Data

Jie Hu |Business Director, HuiTing Technology

Abstract

As model capabilities keep improving, which new kinds of speech data are becoming key resources for the industry? The talk focuses on three hot categories: dialects and minority languages, programming speech, and sleep sounds. Dialect recognition is already an industry necessity — general Mandarin models underperform on dialects and minority languages, and authentic accented corpora are urgently needed to support customer-service, medical and financial scenarios. Demand for programming speech is growing rapidly, while a shortage of dictated-code and technical-instruction corpora constrains related model development. The sleep-sound category is also rising, with soothing audio driving innovation in hearing-health products. HuiTing Technology provides multi-category data collection and annotation services — dialects, minority languages, programming speech, sleep sounds and more — delivering high-quality, compliant corpora for speech foundation-model training and iteration.

Biography

Jie Hu is Business Director at HuiTing Technology, responsible for marketing and strategy execution for speech-data businesses, driving sustained business growth.

04

iFLYTEK

iFLYTEK
Shifu Xiong
Shifu XiongiFLYTEK AI Research
Forum Talk

Progress of iFLYTEK's Spark-Audio Series of Speech Foundation Models

Shifu Xiong |Vice President, iFLYTEK AI Research Institute

Abstract

How can a general-purpose speech foundation connect multiple business capabilities such as recognition, interpretation and intelligent interaction? The talk first introduces the development, key technologies and iteration of the Spark-Audio speech foundation model, then shares technical achievements and application progress in speech recognition, speech interpretation and intelligent voice interaction built on the unified foundation, and outlines directions for the next stage of research.

Biography

Shifu Xiong received his PhD from the University of Science and Technology of China and is Vice President of the iFLYTEK AI Research Institute. He has long worked on speech recognition, interpretation, interaction and speech foundation models, and contributed to products such as iFlytek Input Method, the Jianda meeting transcription system, smart-office-notebook transcription and Spark Xiaoxing chat.

05

OPPO

OPPO AI Center
Min Liang
Min LiangOPPO AI Center
Forum Talk

CuteTTS: Autoregressive Modeling with Continuous Latent Variables

Min Liang |Senior Speech Algorithm Engineer, OPPO AI Center

Abstract

With only 0.2B parameters, can a lightweight TTS model deliver high audio quality, voice cloning and real-time inference at once? OPPO jointly released and open-sourced CuteTTS with Professor Xipeng Qiu's team at Fudan University. The model combines an AudioVAE, a language-model backbone and an AudioDiTHead diffusion decoder, using continuous acoustic latent variables to reduce modeling complexity; guided-step distillation compresses synthesis to four steps; and a lightweight ECAPA encoder with dual-path speaker injection improves timbre control. The talk shares practices in speech quality, speaker similarity, recognition error rate, and deployment across GPU, CPU and Apple Silicon platforms.

Biography

Min Liang is a Senior Speech Algorithm Engineer at the OPPO AI Center with over 10 years of TTS R&D experience across the full stack — text frontend, acoustic models and vocoders — focusing on naturalness, expressiveness, personalization and real interaction experience.

06

ModelBest

ModelBest Inc.
Guoyang Zeng
Guoyang ZengModelBest
Forum Talk

VoxCPM: A Continuous Autoregressive Speech Generation Model

Guoyang Zeng |Co-founder and CTO, ModelBest

Abstract

Without relying on discrete speech tokens, can we explore a more natural and controllable route for speech generation? The talk focuses on the open-source VoxCPM series, introducing a tokenizer-free, continuous autoregressive speech-synthesis architecture that differs from the mainstream discrete-token approach, demonstrating the model's real effects, and discussing technical challenges in multilingual, cross-timbre and high-fidelity generation as well as future directions for speech-generation models.

Biography

Guoyang Zeng is Co-founder and CTO of ModelBest. He participated in developing the CPM series of models and built training and inference tools such as BMTrain and BMInf; he was formerly Deputy Director of the Language Model Acceleration Technology Innovation Center at the Beijing Academy of Artificial Intelligence, and was selected for Beijing's Science and Technology Rising Star Program and Forbes' "30 Under 30 Asia 2026" list.

07

QualiaLabs × NWPU-ASLP

QualiaLabs × NWPU-ASLP
Chengyou Wang
Chengyou WangNWPU-ASLP
Forum Talk

SmoothConv and DuplexConv: Complementary Mandarin Multi-Party Conversation Corpora for Voice Interaction

Chengyou Wang |Master's Student, ASLP Lab, Northwestern Polytechnical University

Abstract

What data and evaluation foundations are needed for voice agents to understand multi-party conversation? The talk introduces SmoothConv and DuplexConv, comprising 2,100 hours of Mandarin multi-party conversation speech. The former provides human-verified data supporting reliable analysis and evaluation, while the latter provides large-scale automatically annotated training data through a scalable pipeline; both include synchronized participant tracks and multi-dimensional fine-grained annotations. The companion SmoothConv Benchmark covers speech separation, multi-speaker ASR and turn-taking detection, providing data and evaluation support for complex multi-party interaction scenarios.

Biography

Chengyou Wang is a master's student in the ASLP Laboratory at Northwestern Polytechnical University, advised by Professor Lei Xie, working on speech recognition, multi-dialect recognition, speech understanding foundation models and full-duplex voice dialogue, and contributing to projects such as WenetSpeech-Wu and FastTurn.

08

MAO KING

MAO KING Audio
Dejun Zeng
Dejun ZengMAO KING
Forum Talk

MAO KING: Building an AI Audio Product Ecosystem and Practice in Innovation

Dejun Zeng |Founder & CEO, MAO KING; Vice President, China Audio Industry Association

Abstract

When a traditional speaker merges with an AI agent, what kind of intelligent-interaction entry point will a listening device evolve into? From the "smart listening" concept to AI smart speakers, the talk reviews MAO KING's explorations in audio technology, products and ecosystem, focusing on applications of AI agents, voice interaction and multimodal emotion perception in proactive interaction, content understanding, scenario services and task execution, and sharing industrial practices in smart audio products, human-machine co-creation and agent-ecosystem collaboration.

Biography

Dejun Zeng is Founder & CEO of MAO KING and Vice President of the China Audio Industry Association. A veteran electroacoustic expert and audio designer with nearly 50 years in the industry, he has won China's National Science and Technology Progress First Prize, nine CES Innovation Awards and a Lifetime Achievement Award of the China audio industry, and participated in drafting multiple audio-industry standards.

09

Anhui Shengyun Intelligence Technology Co., Ltd.

Shengyun Intelligence
Yutian Xie
Yutian XieShengyun Intelligence
Forum Talk

Industrializing On-Device Multimodal Interaction Hardware: The AI Voice-Agent Mouse and Partnership Paths

Yutian Xie |Deputy General Manager, Anhui Shengyun Intelligence Technology Co., Ltd.

Abstract

Can a mouse become a new entry point integrating voice, translation, meeting assistance and agent collaboration? Using the AI voice-agent mouse as a case study, the talk introduces capabilities such as near-field pickup, on-device inference, meeting assistance, real-time translation and coordinated agent invocation, showing how multimodal speech and lightweight-model results are transferred into PC peripherals. It also explores partnership models — technology licensing, university-enterprise joint research and industry customization — providing a practical reference for industrializing AI voice terminals.

Biography

Yutian Xie is Deputy General Manager of Anhui Shengyun Intelligence Technology, responsible for AI business development and industry-academia-research collaboration, with experience bringing multiple AI projects from zero to one, currently focusing on commercializing on-device multimodal hardware.